OpenAI has begun releasing GPT-5.5 in ChatGPT and Codex, with an emphasis on tasks that require several steps and tools. The model was announced on 23 April. An update to the launch page on 24 April says GPT-5.5 and GPT-5.5 Pro are also available through the API.
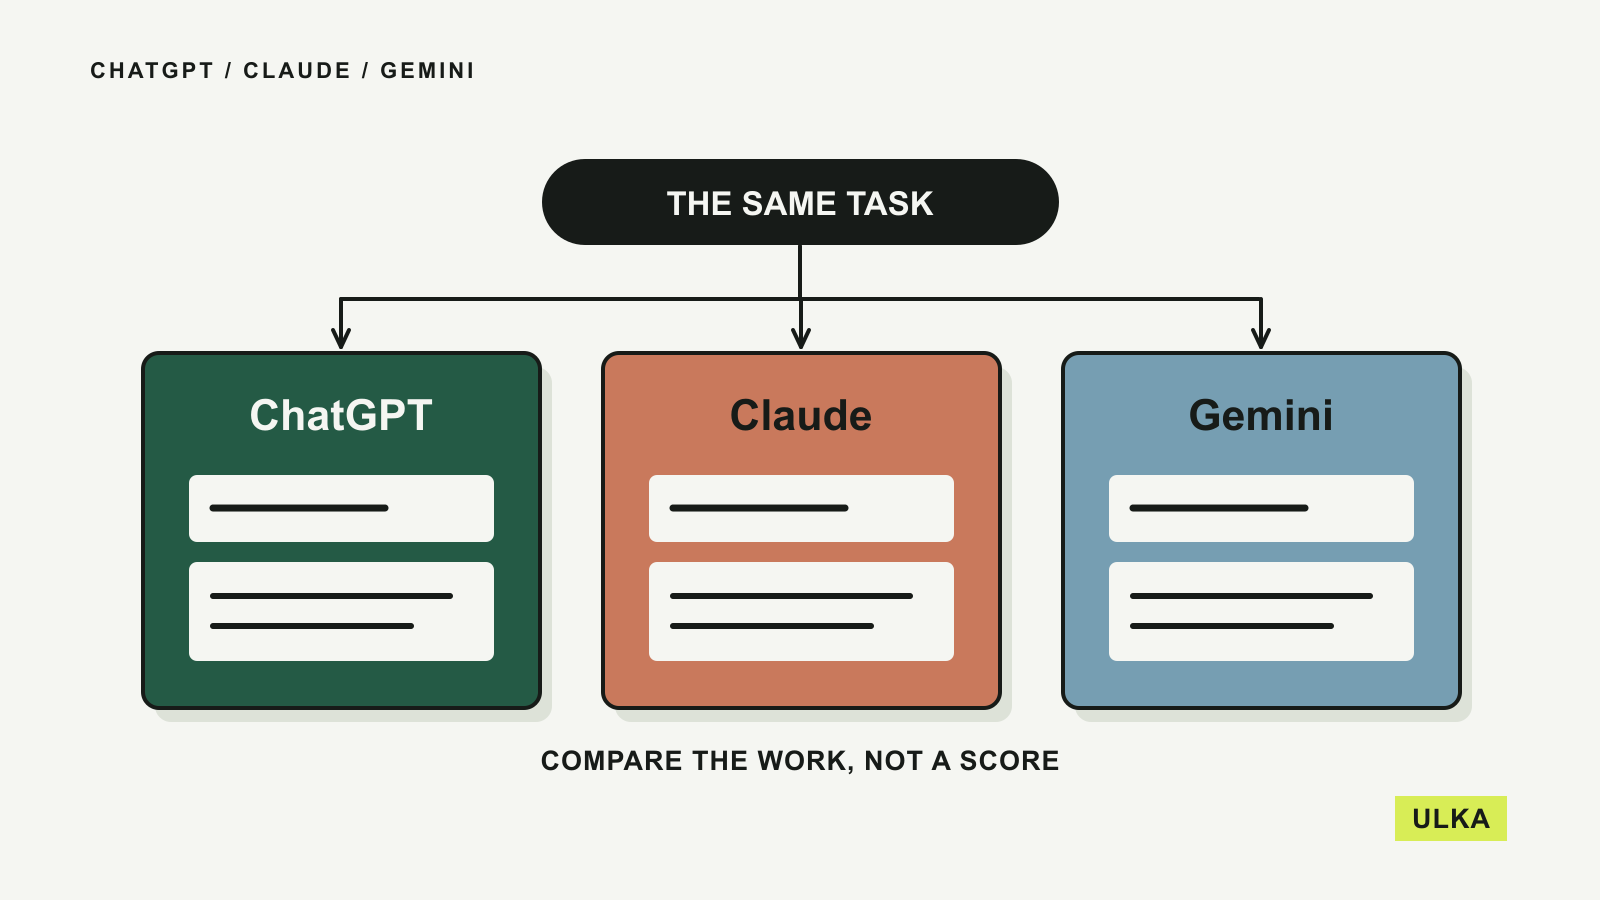
For someone choosing between ChatGPT, Claude and Gemini, the release adds another model to compare. It does not settle which assistant best fits a particular collection of documents, connected applications or working habits.
The launch focuses on completing work
OpenAI describes improvements in coding, research, data analysis, document creation and computer use. The company says GPT-5.5 can carry a task through planning, tool use and checking with less detailed direction. These are claims from the provider’s launch evaluation, and they still need to be tested against the work a reader actually wants to delegate.
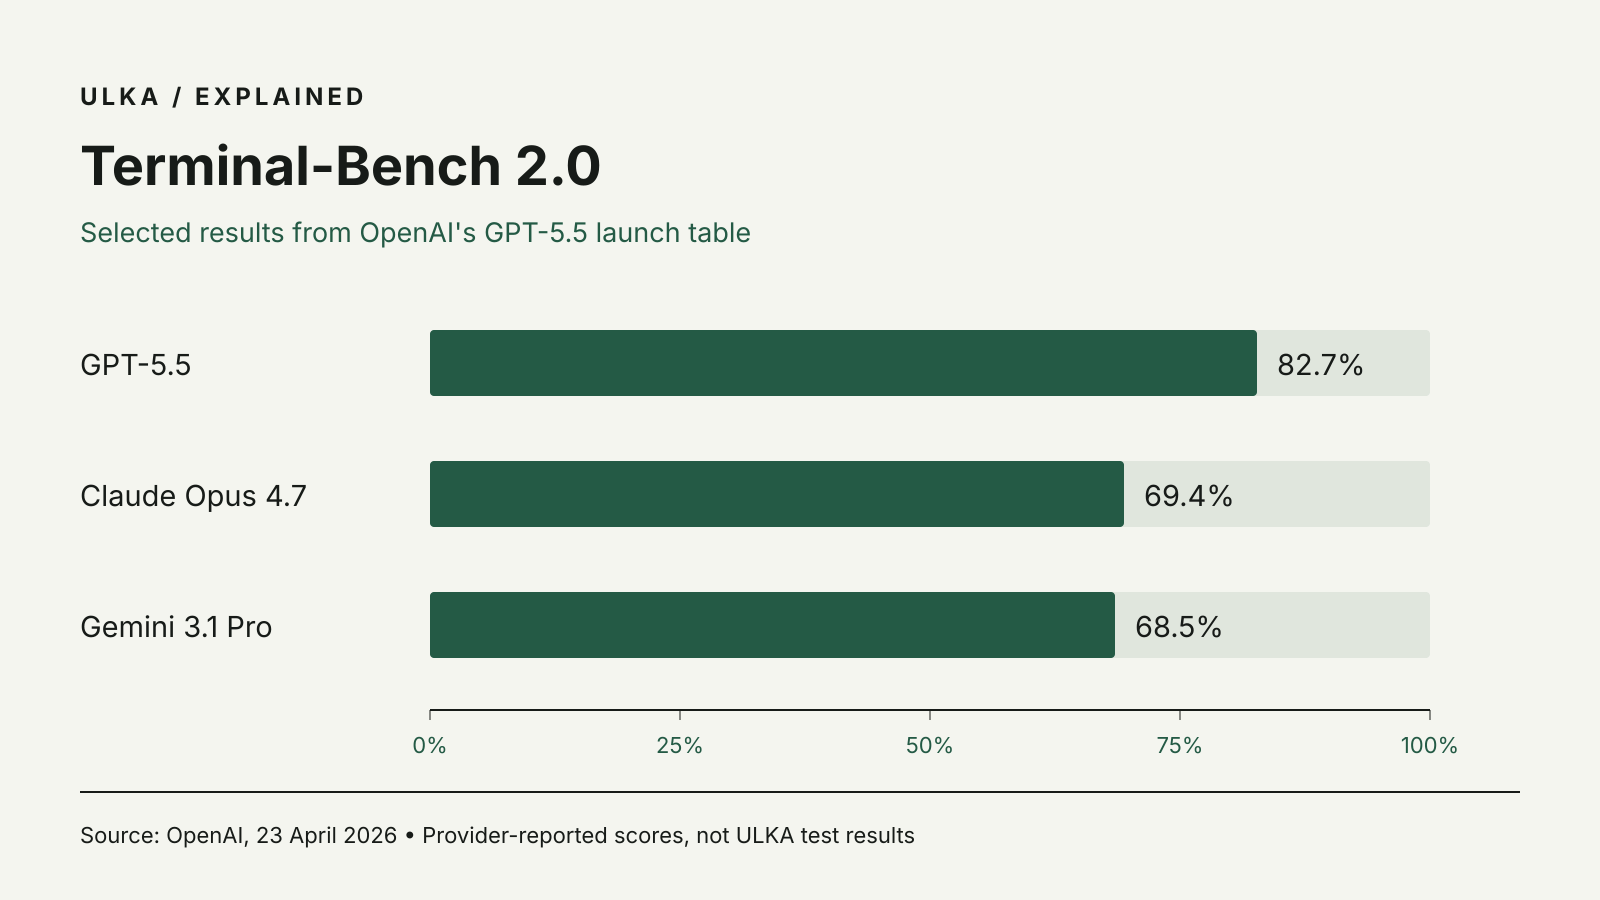
The published benchmark table illustrates why a single winner is an awkward conclusion. OpenAI reports an 82.7 per cent score for GPT-5.5 on Terminal-Bench 2.0, compared with 69.4 per cent for Claude Opus 4.7 and 68.5 per cent for Gemini 3.1 Pro. On BrowseComp, the same table lists 84.4 per cent for GPT-5.5 and 85.9 per cent for Gemini 3.1 Pro, with GPT-5.5 Pro at 90.1 per cent.
Those results concern particular models, evaluation tasks and configurations. They are provider-reported scores, not ULKA testing, and they should not be read as percentages describing everyday accuracy. A benchmark for terminal work also answers a different question from one concerned with finding information online.
Compare the product around the model
The announcement lists GPT-5.5 for Plus, Pro, Business and Enterprise users in ChatGPT and Codex. GPT-5.5 Pro is listed for Pro, Business and Enterprise users in ChatGPT. An API release is a separate way to use a model and should not be confused with the limits or tools attached to a ChatGPT subscription.
If you already use an assistant, choose one repeatable task before considering a switch. Supply the same source documents, define the required result and record the corrections you need to make. For a spreadsheet, that might mean checking the calculations and file you receive; for research, it means checking that the cited material supports the answer.
Keep access to sensitive applications limited during that comparison. A model’s ability to use more tools increases the importance of deciding which actions it may take and which require review.
The useful comparison is the amount of dependable work each service delivers within your budget and account limits. Follow this question in ChatGPT vs Claude vs Gemini.
Source: OpenAI, “Introducing GPT-5.5”, 23 April 2026, including the API availability update of 24 April. Chart values are OpenAI-reported Terminal-Bench 2.0 results, not independent ULKA measurements.